Google announced Gemini 4 Argon on 30 September, its new top model, and the long-awaited answer to GPT-6 Astra and Claude Opus 5.5. By Google's own tests it leads on most of the work a business actually pays for: finance research, legal drafting, long documents and end-to-end office tasks. Three facts matter more than the headline. Almost nobody can use it yet. The price on the announcement is an introductory price that doubles later. And the first independent score puts it level with OpenAI's flagship, not clearly ahead of it. This article sets out what Argon costs, what it scores and where it loses. It also covers what a business owner should do in the weeks before it opens up.
What Google released on 30 September, and who can use it today
Google DeepMind calls Argon a model "built to sustain deep reasoning across complex, long-horizon workflows". In plain terms, it is designed for long jobs with many steps, not quick chat answers. Google says it is aimed at three kinds of work: software engineering, "enterprise knowledge work like legal and finance", and cybersecurity defence.
- Who has it now. A small group of "trusted cyber defenders" in Google's Fairwind Program. For them, Google is releasing a version without its usual cyber guardrails, so they can use it to find and patch software flaws.
- Who gets it next. Google says it will reach developers, enterprises and consumers "as soon as possible", starting with paid Gemini API customers and Google AI Ultra subscribers. It gives no date.
- Why the wait. Google says it is taking part in the U.S. government's voluntary pre-release access process and wants feedback from early testers before it widens access.
- What is new under the hood. Argon can write up to 1 million tokens in a single answer, up from 64,000 on Google's previous models. A token is roughly three quarters of a word.
On 1 October, Argon was not on the Gemini API price page, which still led with Gemini 3.8 Flash. Treat everything below as planning, not as something you can switch on this afternoon.
The price: $2 and $10 now, $4 and $20 later
Google says Argon "will launch at an introductory price" of $2 per million input tokens and $10 per million output tokens, with cached input at 95% off. The footnote matters more than the headline: once the introductory period ends, the price becomes $4 in and $20 out. Google has not said how long the introductory period lasts.
Here is how that compares with the models you can actually buy today, per million tokens:
| Model | Input | Output |
|---|---|---|
| Gemini 4 Argon (introductory) | $2.00 | $10.00 |
| Gemini 4 Argon (after intro) | $4.00 | $20.00 |
| Claude Opus 5.5 | $4.00 | $20.00 |
| GPT-6 Astra | $10.00 | $50.00 |
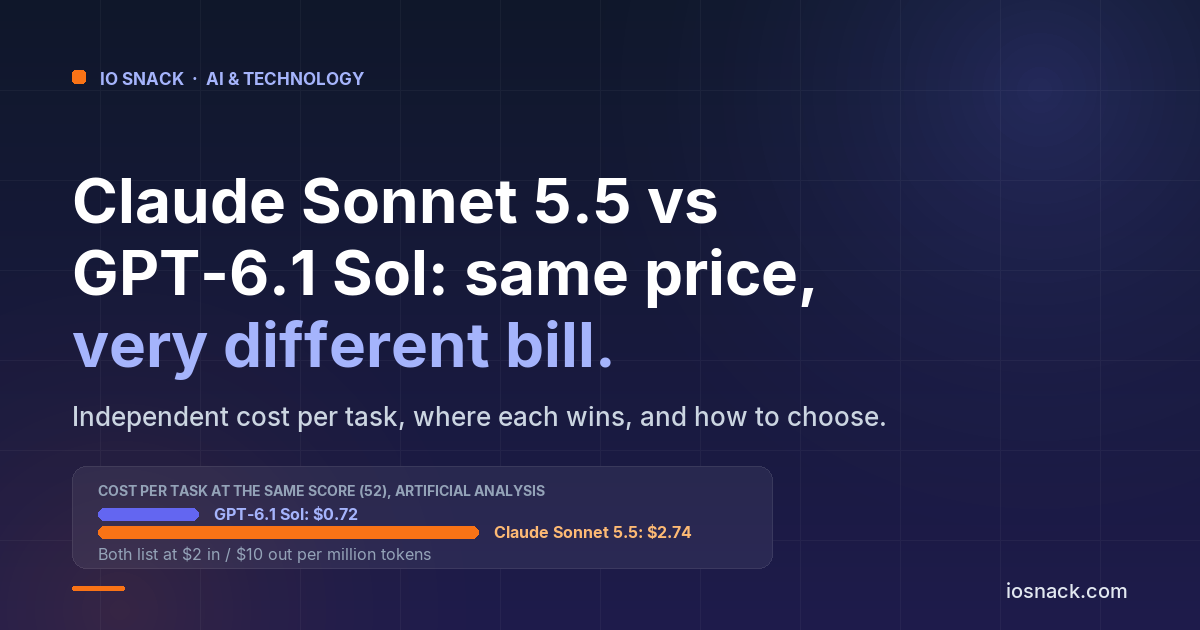
| Claude Sonnet 5.5 | $2.00 | $10.00 |
| GPT-6.1 Sol | $2.00 | $10.00 |
| Gemini 3.8 Flash | $0.75 | $3.75 |
So for now, Google is selling its flagship at the price of the mid-tier "workhorse" models: Claude Sonnet 5.5 and GPT-6.1 Sol. At full price, it lands exactly on Claude Opus 5.5, and still well below GPT-6 Astra.
For a subscription rather than the API, the route in is Google AI Ultra. Seen from Pakistan on 1 October, Google's subscriptions page lists AI Ultra from Rs 21,999 a month (five times AI Pro's usage limits), with a higher tier at Rs 55,900 a month (twenty times). AI Pro is Rs 5,600 and AI Plus is Rs 1,400. Google has not said which Ultra tier gets Argon first, so do not upgrade on the strength of this announcement alone.
Budget for the price in the footnote, not the headline: Argon is a $4-in, $20-out model being sold at half price for a while.
Google's own benchmarks: where Argon wins, and where it does not
Google DeepMind publishes a comparison table on its Gemini model page. Every number below is Google's, from Google's own runs, not an independent check. By our count of that table, Argon has the top score on 13 of its 19 rows, ties on one, and loses on five. The wins are concentrated in exactly the kind of work an owner or finance team would hand over.
| Test (Google's numbers) | Argon | GPT-6 Astra | Opus 5.5 |
|---|---|---|---|
| Vals Index (finance, coding, legal, tax) | 68.9% | 63.1% | 67.0% |
| Vals Finance Agent v2 | 65.4% | 53.5% | 58.6% |
| Harvey Legal Agent Benchmark | 19.6% | 5.4% | 3.8% |
| AutomationBench (Zapier) | 51.3% | 41.4% | 42.5% |
| DeepSWE v1.1 (coding) | 77.9% | 74.1% | 74.2% |
| Chartography (reading charts) | 71.6% | 71.0% | 66.3% |
| FrontierSWE v2 (coding) | 55.0% | 65.5% | 62.3% |
| Terminal-bench 4.0 | 57.4% | 58.2% | 66.4% |
| OSWorld-2.0 (computer use) | 69.2% | 72.6% | not listed |
What the wins mean
- Finance and legal work. Vals Finance Agent tests multi-step financial research. Harvey's benchmark tests legal research and drafting. Argon's legal score is low in absolute terms, but nearly three times the next best in Google's table (Claude Fable 5.1, at 6.7%). Google is clearly aiming at the back office.
- Office automation. AutomationBench, built by Zapier, measures whether a model can carry a business task through from start to finish. Argon scores 51.3%, nearly nine points ahead of Opus 5.5. That is a real lead, but a score of about half still leaves a lot of room. It is not a solved problem.
- Charts, documents and video. Google says Argon is state of the art on LVBench (long video understanding) at 91.7%, and leads on reading charts. That is relevant if your work lives in scanned statements, reports and dashboards.
What the losses mean
- Operating a computer. Argon trails GPT-6 Astra on OSWorld-2.0 and trails both rivals on Terminal-bench 4.0. Both test an agent driving a real computer or terminal step by step. If you are building an agent that clicks through websites or runs commands, Google's own table says Argon is not the leader.
- Some coding. It wins DeepSWE but loses FrontierSWE v2 by ten points to Astra. Coding results depend heavily on the test. Run your own before you move a development team.
The first independent number: level with GPT-6 Astra, not ahead
Vendor benchmarks are chosen by the vendor. Artificial Analysis is an independent company that runs every major model through the same set of ten tests and publishes two numbers: an Intelligence Index score, and the average cost of completing its test tasks at the model's real prices. It had already listed Argon on 1 October.
- Score. Argon (at high effort) scores 53, ranked 8th of 223 models. GPT-6 Astra at max effort also scores 53. Claude Opus 5.5 scores 58 at max effort and 54 at high effort.
- Cost per task. $1.99 at the introductory price. Artificial Analysis notes Argon is "somewhat verbose": it used 110 million output tokens to run the index, against a median of 82 million.
- Speed. Not published yet, which fits a model that only a few testers can reach.
Here is what it costs to reach the same level of capability with each model, from the Artificial Analysis leaderboard on 1 October:
Read that chart carefully, because it changes the story. At the introductory price, Argon is good value for a flagship: it matches GPT-6 Astra's score for well under Astra's cost. But Claude Opus 5.5 at high effort scores a point higher for a little less money. GPT-6.1 Sol gets within one point for about a third of the cost. And once the introductory price ends, Argon becomes the most expensive way on this chart to reach that level.
Two caveats in Argon's favour. First, a general index averages many kinds of work. Argon's lead in Google's table is in finance, legal and document work, so it could do better on your jobs than its average suggests. Second, early access listings are sometimes re-tested. We will refresh these figures when Argon opens to paying customers.
A million-token answer is a feature and a budget risk
The change from a 64,000-token output limit to 1 million tokens sounds technical. It is really about money. Output is the expensive side of the price list, and a model allowed to write a million tokens can, in principle, bill you for a million tokens in a single answer.
- The arithmetic. One million output tokens costs $10 at Argon's introductory price and $20 at the full price. That is a single request, before any input, retries or follow-up steps.
- Why it happens in practice. Long agent runs, "think as long as you need" settings and loops that keep asking for more are exactly how a fixed-price task turns into a surprise bill. Artificial Analysis already flags Argon as more verbose than average.
- The fix is boring and it works. Set a maximum output length on every request, set a monthly spending cap in the provider's console, and log the cost of each job, not just the monthly total. These are the same guardrails we would put on any model. A higher ceiling just makes them more important.
Where the long output earns its cost is the job you currently split into ten pieces: a full migration, a long report, a complete set of documents from one brief. Google's examples are internal: Argon agents moving large C and C++ codebases to Rust, and finding memory optimisations that Google says free up over 300 TiB across its data centres once rolled out. Those are Google's own claims about its own work. They show the kind of job the model is built for, not a result you should expect on day one.
What a business owner should do before it opens up
The worst response to a launch like this is to pause everything and wait. Argon has no date. The models you can buy today are, on independent numbers, within a point or two of it. Here is how we would use the waiting time.
- Do not stop a project you have already started. If something works on GPT-6.1 Sol, Claude Sonnet 5.5 or Opus 5.5 today, keep shipping it. Switching models later is a configuration change if you build for it, and a rewrite if you do not.
- Build a small test set from your own work now. Twenty real tasks with known good answers: reconcile a bank statement, summarise a contract, answer ten real customer questions, read five supplier invoices. When Argon opens, run the same twenty through it and your current model, and compare quality and cost per job. That beats any benchmark table, including Google's.
- Price your plan at $4 and $20. If a workflow only makes financial sense at the introductory price, it does not make sense.
- Watch the finance and legal results first. That is where Google claims the biggest lead, and where a better model saves the most staff time. If an independent tester confirms that lead, Argon becomes a serious option for bookkeeping, document review and research work.
- Do not buy AI Ultra just to get Argon. At Rs 21,999 a month from Pakistan, Ultra only makes sense if you already need the rest of the bundle. Google has not even confirmed which Ultra tier gets Argon first.
Where this leaves the Gemini, ChatGPT and Claude choice
On 1 October, the Gemini API price page still led with Flash models, which are built to be fast and cheap. Argon is Google's answer at the top end. On Google's own numbers it leads most tests, and on the one independent score it has drawn level with OpenAI's flagship. That makes this a three-way race at the top again, which is good news for anyone paying the bills.
For most small and medium businesses, though, the decision this month has not changed. The cheapest model that does your job well is still the right one, and independent cost per task is still the number to choose by. We compared the two newest mid-tier models in Claude Sonnet 5.5 vs GPT-6.1 Sol, and the subscription prices in rupees in ChatGPT vs Claude vs Gemini in Pakistan. We will update that comparison when Argon reaches paying customers. For API prices across every major vendor, including the Gemini Flash rise coming in January, see AI API pricing for 2027.
If you want the benefit of these models without managing them yourself, that is what our products are for. The AI Chat Assistant answers customer questions on your website and hands complex chats to your team on WhatsApp. IO Snack Accounts uses AI to categorise entries and flag anomalies as you post them, which is the kind of finance work Argon is being aimed at. If you are planning something bigger and want a second opinion on which model fits it, talk to us.